Product photos to ad videos
The product photo fixes the look, selling points go in as text images, the presenter and voice-over go in the prompt: one request, one complete ad; billed per second, so making several is cheap.
Seedance 2.5 Flash is the video model ByteDance released in November 2026, the Flash version of Seedance 2.5. Send a prompt, optionally with up to 10 reference images, 5 reference videos and 5 reference audio clips, and get a 4-30 s clip at 480P or 720P with dialogue and sound effects generated with the picture. On KovAPI it is seedance-2.5-flash: 720P $0.12/s, 480P $0.06/s, and a 30-second 720P clip costs $3.60. In our November tests 480P took about 2 minutes and 720P 4-8 minutes. There is no 1080P, and images are references, never a first frame.
Try out Seedance 2.5 Flash right here (available after login).
The prompt, the reference files and the finished clip all go through content review, picture and sound alike.
A rejected job is not charged; the credits held at submit are refunded in full.
Some jobs are rejected at submit; others only when the finished clip is reviewed, anywhere from a few minutes to over half an hour later.
Spoken lines, narration and lyrics in your prompt are voiced or sung, and reviewed together with the picture. If you need no voices, leave out lines and lyrics. This model always adds a soundtrack; it cannot be turned off. Uploaded reference audio is reviewed as well.
Sexual content or nudity; gore, self-harm and violent injury such as gunshot wounds; firearms, explosives and drugs; minors shown with alcohol, tobacco or in danger; politicians, celebrities and other public figures, in looks or voice (look-alikes included); copyrighted characters.
If a single shot in a long storyboard script breaks the rules, the whole clip is rejected. Resubmitting the same input is rejected again; fix that part or replace the reference, then retry.
Every preview below is cut from a clip on this page. "See the full case" opens the original with sound, its prompt, settings and cost.
Up to 30 s per clip, with shots placed on whole-second timestamps. The guardian robot clip uses a nine-panel storyboard and three design sheets to cover a farewell, a rocket launch, an explosion and the old woman's cry in 30 seconds, with English lines in sync.
Up to 10 reference images, each with one job: a person, a set, a prop. The family drama uses six character turnarounds and two set images, numbered in order of first appearance, and the ticket window, the counting of the money and the children's cheer all keep the right faces.
Upload a simple untextured 3D blockout and the model follows its motion and camera while painting in the scene and character from the prompt. This one used a six-second blockout and one line of render notes; the 30-second 3D animation adds nine key frames for each stretch. Reference-video seconds are billed too.
Every clip has a soundtrack. A reference audio clip sets a character's voice: this one uses a line of Granny Zhou cut from a Seedance 2.5 clip, and the new lines Flash wrote for her keep that voice. Reference audio must come with a reference image or video and is not billed.
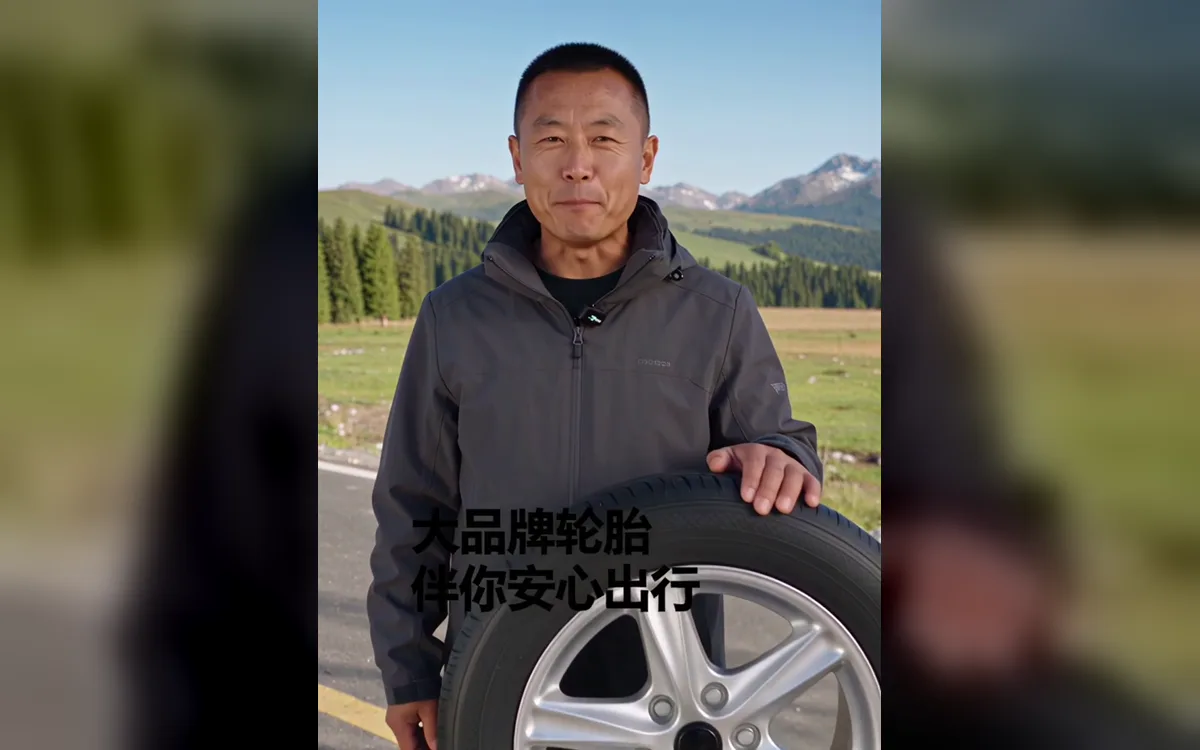
The product photo fixes the look, the selling points go in as text images, and the presenter and voice-over are written in the prompt: one 16-second vertical ad per request. Flash got most of the big captions right but miswrote two characters in one vertical line; if on-screen text must be exact, see the comparison with Seedance 2.5 below.
Hover to play the clips together; on a phone tap "Play together". Prompt, references, length and ratio are identical, each clip was rendered on its own, so the pictures differ: compare motion, faithfulness and detail. Under each clip is what that clip costs at today's price.
On a plain text prompt the two are close: Flash 720P rolls more playfully, Seedance 2.5 shows a little more fur detail; Flash 480P keeps the framing and motion but turns soft when enlarged -- fine for a first look.
Flash 720P: the roll, the sit-up and the look to camera are all there, at about three quarters of the 2.5 rate.
Seedance 2.5 720P: calmer motion, slightly more fur and light detail.
Flash 480P: half the 720P price, good for drafts in bulk.
写实自然纪录片风格,电影级真实光影,温暖的午后, 在森林草坡上, 一只圆滚滚的熊猫幼崽从坡上滚下来.

熊猫黑白毛发蓬松真实,体型小而胖,动作笨拙可爱。场景为绿色森林斜坡,地面覆盖青草、苔藓、三叶草、泥土、小石块、枯枝和少量小黄花,虚化背景中有高大树干与树林。镜头为低机位中远景,轻微手持感,整体基本固定,始终保持熊猫在画面中。

0s-3s:一只熊猫幼崽趴在绿色草坡上,身体圆滚滚, 它刚开始顺着斜坡慢慢侧滚,动作笨拙,草叶被身体轻轻压弯。微风拂过, 阳光从左上方穿过树林,形成斑驳光影。
3s-8s:熊猫滚到画面右下方,动作逐渐停止,从侧躺变成趴卧。它的圆脸朝向镜头,前爪压在草地上,熊猫趴在前景草丛中,身体调整到舒服的姿势,头部小幅抬起又放低, 发出轻微哼唧声。

低机位,轻微手持感,轻微跟随熊猫向右下方移动。景深自然,前景草叶轻微虚化,熊猫主体清晰,背景树林柔和虚化。自然环境音,风声、熊猫滚动时轻微柔软的扑通声, 整体温暖、真实、自然。
Read in English · The translation is for reading only; Copy and Use send the original
Realistic nature-documentary style, cinematic natural light, a warm afternoon: on a grassy forest slope, a chubby panda cub rolls down the hill.

The cub's black-and-white fur is fluffy and real; it is small and plump, clumsy and cute. The slope is green, covered with grass, moss, clover, soil, small stones, dry twigs and a few small yellow flowers, with tall trunks and woods in the blurred background. Low-angle medium-long shot with a slight handheld feel, mostly static, always keeping the panda in frame.

0s-3s: the cub lies on the green slope, round as a ball, and starts to roll slowly sideways down it, clumsily, gently pressing the grass flat. A breeze passes; sunlight comes through the trees from the upper left in dappled patches.
3s-8s: it rolls to the lower right of the frame and comes to a stop, turning from its side onto its belly. Its round face turns to the camera, front paws on the grass; lying in the foreground grass it settles in, lifts its head a little and lowers it again, with a soft grunt.

Low angle, slight handheld feel, gently following the panda to the lower right. Natural depth of field: foreground grass slightly soft, the panda sharp, the woods softly blurred. Natural ambience: wind and the soft thuds of the rolling panda; warm, real and natural throughout.
Both drew the tyre from the photo and followed the voice-over and shots in the prompt. The difference is the on-screen text: Seedance 2.5 got all four selling-point captions right; Flash wrote one vertical line wrong (two characters) and its reading order is a little off.
Flash: presenter, tyre and voice-over right; one vertical caption wrong.
Seedance 2.5: all four captions right, cleaner layout.
为图1中的商品生成视频,由中国中年自然肤色黑色寸头日常户外风男模特出镜,手持商品进行动态展示与解说。镜头 1,镜头从中景缓慢推进至近景。阳光明媚的广阔户外公路旁,一位中国中年、自然肤色、黑色寸头、穿着日常户外冲锋衣的男模特,一手扶着立在地上的大品牌轮胎,面向镜头自信地进行解说。 男主播:“大品牌轮胎,伴你安心出行。” 背景音乐:节奏轻快的户外运动风纯音乐。 画面正下方显示粗体黑字“大品牌轮胎 伴你安心出行” 参考图2。镜头 2,镜头特写轮胎正面花纹。男模特的手指顺着轮胎上深深的纵向排水沟槽滑动,随后手掌有力地拍打胎面,动态展示轮胎清晰的纹理和扎实的质感。 男主播:“强效排水,稳健抓地。” 背景音乐持续,伴随轻微的摩擦音效。 画面左侧弹出黑体大字“强效排水 稳健抓地” 参考图3。镜头 3,镜头平移转至轮胎侧面特写。男模特用手掌按压轮胎侧壁展示其优良的韧性与弹性,随后手指指向侧面凸起的品牌标识区域。 男主播:“静音舒适,坚韧耐用。” 背景音乐持续。 画面右侧弹出黑体大字“静音舒适 坚韧耐用” 参考图4。镜头 4,镜头拉远回到中景。男模特双手扶住轮胎边缘,轻松地将其向前滚动半圈,随后站定,微笑着向镜头竖起大拇指,背景是充满活力的自然风光。 画外音:“你的安心之选。” 音乐高潮处有力收尾。 画面中央浮现黑体大字“伴你安心出行” 参考图2
Read in English · The translation is for reading only; Copy and Use send the original
Make a video of the product in image 1: a Chinese middle-aged male model with natural skin, short black hair and everyday outdoor clothes presents and explains it on camera, product in hand. Shot 1: the camera slowly pushes from a medium shot to a close shot. Beside a wide outdoor road on a sunny day, the model, in an everyday outdoor shell jacket, rests one hand on a big-brand tire standing on the ground and speaks to the camera with confidence. Presenter: "大品牌轮胎,伴你安心出行。" (A big-brand tire for worry-free trips.) Music: light, upbeat outdoor-sports instrumental. Bold black text at the bottom centre: "大品牌轮胎 伴你安心出行" — see image 2. Shot 2: close-up of the tread. His fingers run along the deep lengthwise drainage grooves, then his palm slaps the tread firmly, showing the clear pattern and solid build. Presenter: "强效排水,稳健抓地。" (Strong drainage, steady grip.) Music continues with a light rubbing sound. Big black text pops up on the left: "强效排水 稳健抓地" — see image 3. Shot 3: the camera pans to a close-up of the sidewall. He presses the sidewall with his palm to show its toughness and spring, then points at the raised brand area. Presenter: "静音舒适,坚韧耐用。" (Quiet and comfortable, tough and lasting.) Music continues. Big black text pops up on the right: "静音舒适 坚韧耐用" — see image 4. Shot 4: the camera pulls back to a medium shot. He holds the tire's edge with both hands, rolls it forward half a turn with ease, stands still and gives the camera a smiling thumbs-up against lively scenery. Voice-over: "你的安心之选。" (Your worry-free choice.) The music ends on a strong climax. Big black text appears in the centre: "伴你安心出行" — see image 2.
The more key frames that must be matched one by one, the clearer the gap: Seedance 2.5 hit the logo, the pixel scatter, the martial-arts manual, the hero and the event screen in order; Flash skipped the manual and put in a close-up of the hero instead, keeping the rest in order.
Flash: one take and the pixel style are right; one key frame unused.
Seedance 2.5: all six key frames matched.
根据 @图片1 - @图片6 制作一镜到底的像素武侠主题竖版视频,背景音乐使用国风 8bit 武侠风格音乐。全片统一浅蓝底色,像素风格统一,画面干净通透。
镜头 1:静止展示 @图片 1 的「江湖风云」水墨风格 logo,背景为统一浅蓝底色,画面保持约 1 秒静止。
镜头 2:@图片 1 中的文字区域消失后,@图片 2 的武侠男性角色像素脸部特写从画面底部滑入;角色眨眨眼看向镜头,随后快速向下位移离场;角色离场后,原本 logo 处变为 @图片 3 的蓝色「武功秘籍」像素书。
镜头 3:紧接 @图片 4,像素武侠小人角色从画面下方用力向上跃出,顶起上方的蓝色菱形问号标,问号标上方弹出深蓝色粗体字「今日闯江湖!」;角色落地后摆出 @图片 4 的站姿 pose,随后抬手打招呼,接着做出预备跑动作,转身向画面右侧奔跑(奔跑姿态参考 @图片 5),镜头跟随角色向右移动,角色从画面右侧跳出画面。
镜头 4:@图片 6 的 UI 界面从画面右侧位移入画,像素武侠角色从画面右上角跳入,落在「三月廿七日」大字的右下方,张开双臂摆出热情展示的定格姿势,最终定格在该画面。
整体像素武侠美术风格,色调统一浅蓝底,运镜连贯顺滑呈现一镜到底的连续位移与跟随,元素过渡自然、角色动作衔接流畅,画面无卡顿、无闪烁;文字与 UI 清晰稳定。
Read in English · The translation is for reading only; Copy and Use send the original
Using @Image1 - @Image6, make a one-take vertical video on a pixel-art wuxia theme, with Chinese-style 8-bit wuxia music. The same light-blue background throughout, one pixel style, clean and clear.
Shot 1: a still of the ink-style "江湖风云" logo from @Image 1 on the light-blue background, held for about 1 second.
Shot 2: the text of @Image 1 disappears and the pixel face close-up of the male wuxia hero from @Image 2 slides in from the bottom; he blinks, looks at the camera and quickly drops out of frame; the logo's place becomes the blue pixel book "武功秘籍" (martial-arts manual) from @Image 3.
Shot 3: straight into @Image 4: the little pixel hero leaps up from the bottom and bumps the blue diamond question-mark block above, which pops up the dark-blue bold words "今日闯江湖!" (into the jianghu today!); he lands in the standing pose of @Image 4, waves, crouches to run, turns and runs to the right (running pose as in @Image 5); the camera follows him right and he jumps out of frame on the right.
Shot 4: the UI screen of @Image 6 slides in from the right; the hero jumps in from the upper right, lands to the lower right of the big date "三月廿七日" (the 27th of the third month), throws his arms open in an eager presenting pose and freezes there.
Pixel wuxia art throughout on a uniform light-blue background, smooth continuous moves and follows in one take, natural transitions between elements, fluid character motion, no stutter or flicker; text and UI sharp and stable.
The product photo fixes the look, selling points go in as text images, the presenter and voice-over go in the prompt: one request, one complete ad; billed per second, so making several is cheap.
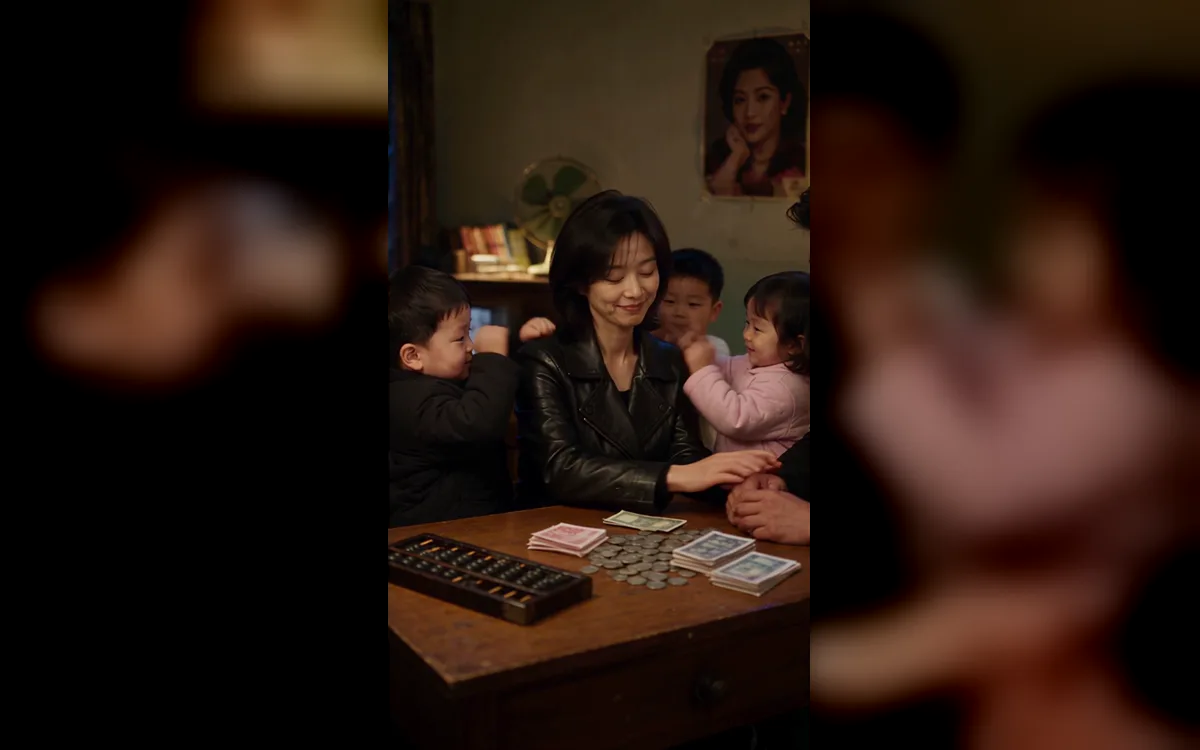
Upload character turnarounds and set images separately and give each shot its size, camera and one line of dialogue: good for drama samples and story previs.
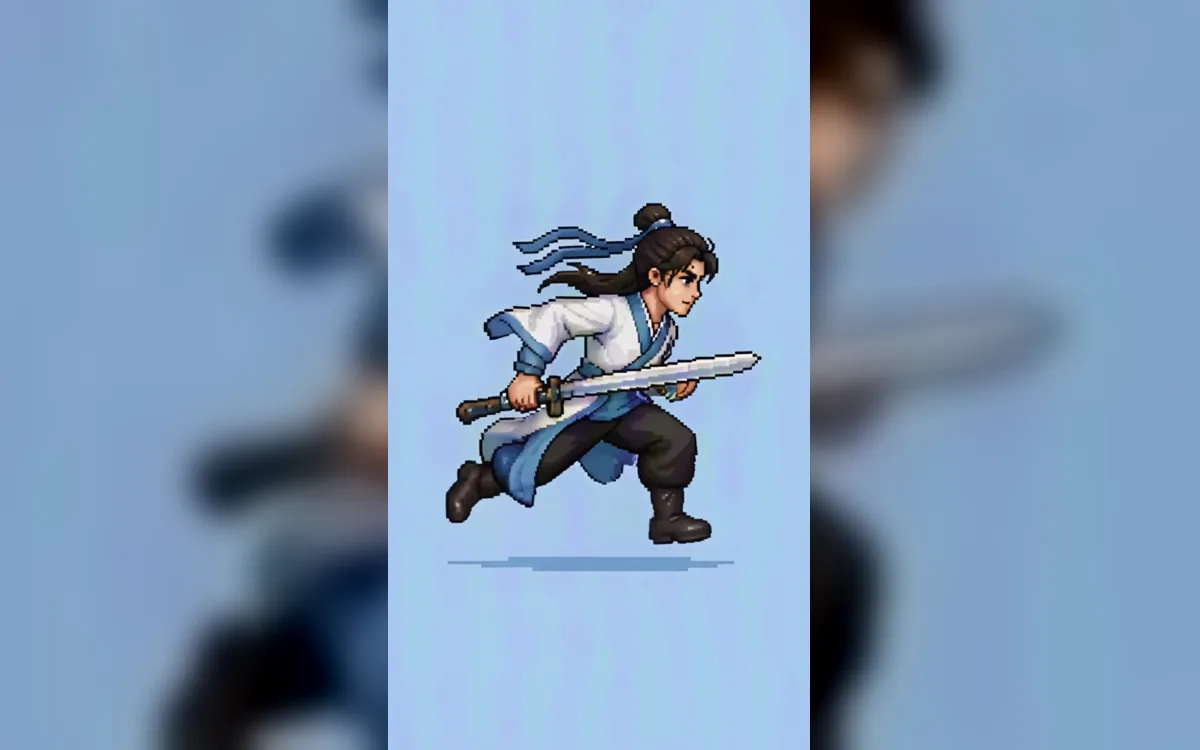
Feed the logo, characters, props and UI as ordered key frames for a one-take opener or an event teaser.
Block out motion and camera with simple shapes, then let the model render the full picture from your prompt: no detailed modelling or rendering.
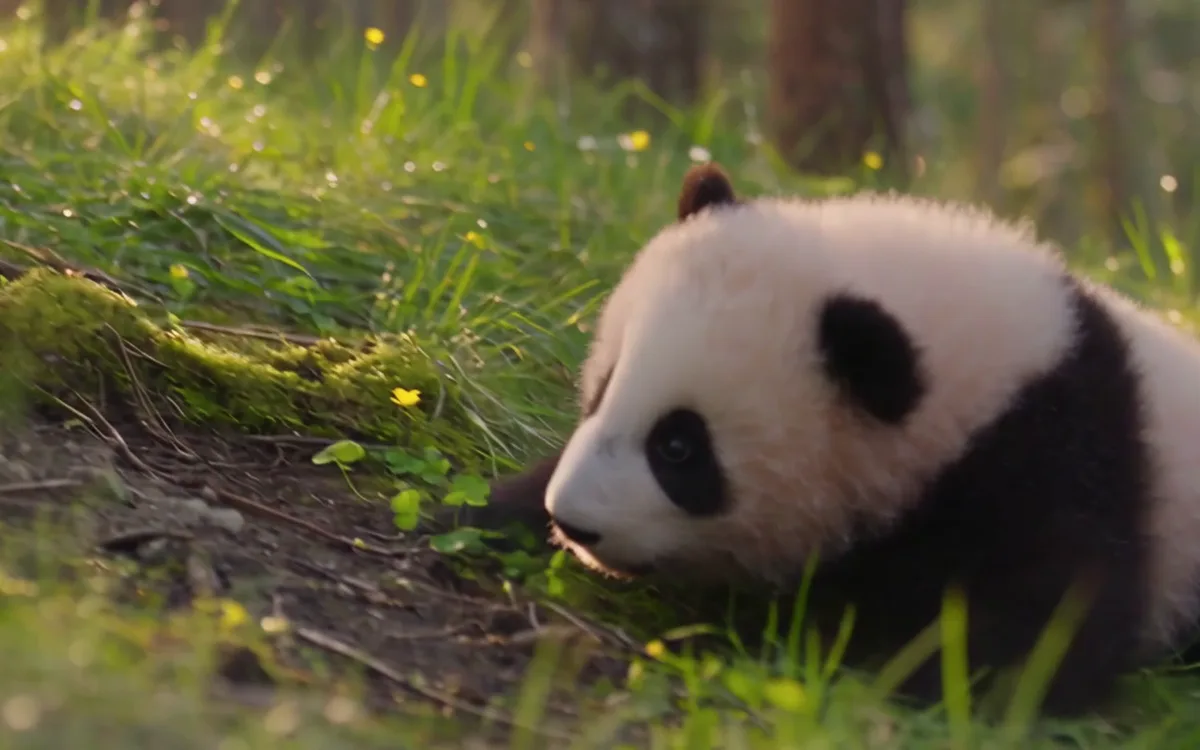
Run the same prompt and references through Flash a few times, pick the direction you like, then render the final with seedance-2.5 (1080P or stricter shots) by changing only model.
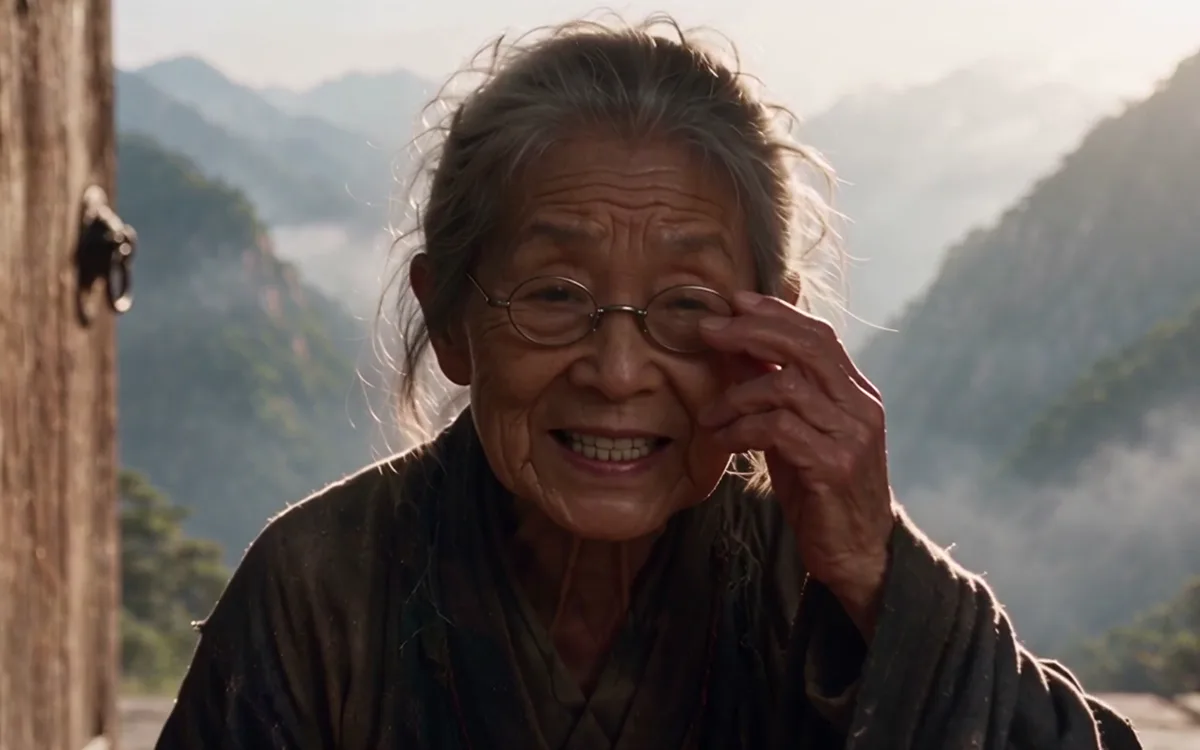
Cut one line of a character from the last episode as reference audio and add their image: the next episode keeps the voice and the look.
seedance-2.5-flashPOST https://kovapi.com/v1/videos/generations → GET https://kovapi.com/v1/videos/jobs/{id}All modes share model (seedance-2.5-flash), prompt, duration, resolution and size. Images, videos and audio can go in one request; each kind is numbered in upload order and named in the prompt as @Image1, @Video1, @Audio1.
| Mode | Send | You get | Limits |
|---|---|---|---|
| Text to video | Only prompt and the settings, no references. | Picture, motion and sound from the text; write dialogue, effects and music into the prompt. | Only the general limits (see the specs). |
| Multi-image reference to video | images in order; the prompt says what each image is for: a person, a product, a set, a style, a storyboard or a key frame. | New footage that follows the references' look, framing or storyboard; several characters can appear together. | Up to 10 images, 300-6000 px a side, aspect 0.4-2.5. Every image is a reference, never a first frame. |
| Reference video to video | video_references with video links (images may come too); the prompt says whether to follow the motion, the camera, the pacing or a blockout. | The reference's motion and camera with new characters, sets and style; a 3D blockout can be rendered into finished footage. | Up to 5 videos, 30 s in total; reference-video seconds are billed (see pricing). |
| Reference audio | audio_reference with audio links plus a reference image or video; the prompt says whether to follow the voice, the lines or the music. | A character speaks new lines in the reference voice, or the picture follows the reference music's rhythm. | Up to 5 clips, not billed; must come with a reference image or video. |
@Image2, the first audio clip @Audio1.prompt is capped at 11,000 characters; Chinese and English count the same, punctuation, spaces and line breaks included.Based on Volcengine Ark's Doubao Seedance 2.5 prompt guide (English edition on BytePlus): assign the references, sum the clip up in one sentence, lay the action out on a timeline, then add the camera, setting and sound that run through the whole clip. Flash takes the same prompts as 2.5. The examples below are quoted from the prompts of the examples on this page, which come from that guide.
Images, videos and audio are each numbered in upload order. Say what every reference is for: whose look, whose voice, which motion, which place; when only part of a reference matters, say which part.
Guardian robot: "image3: subject 1 (the guardian robot), appearance reference".
Subject, place, event, genre and any special camera move come first, so the model has the whole picture before the details.
Panda: a realistic nature-documentary shot of a chubby panda cub rolling down a forest slope on a warm afternoon.
Seedance 2.5 follows timestamps in whole seconds. Keep the ranges continuous and describe picture, camera, action, lines and sound per range; packing too much into one range gets it cut up.
Panda: "0s-3s ... 3s-8s ...", one action per range.
Write lines as "character (mood): text", one per line. Repeating a line with a note on its tone right after it tends to bring on subtitles.
From the guide: Granny Zhou (voice trembling): "So alike."
"No subtitles" and "no background music" are followed; describe the picture in positive terms. To rule music out completely, list its synonyms and say it at both the start and the end.
From the guide: "no BGM, only ambient sound and action sounds".
With several characters, upload their references in the order they first appear and keep the numbers in the prompt matching; that keeps faces and voices from swapping.
Family drama: "image 1 → Qin Xiulian, image 3 → Liu Chunxiang ..."
Text that must be spelled right goes in as a reference image; English words can also be spelled out letter by letter.
Tire ad: the on-screen caption "强效排水 稳健抓地" ("strong drainage, steady grip") is followed by "see image 3".
References far sharper than the output occasionally leave fingerprint-like texture on grass or leaves; scaling them to the output resolution lowers the odds.
The references of the examples here were scaled to 1280 px on the long side for 720P clips.
Four images, one job each: shot structure, location, and the look of each of the two characters. Numbers follow the upload order.
"image1: nine-panel storyboard reference" (sets the shot structure, shot sizes and pacing).
One paragraph per character: look, build, relative height. Later shots only describe action.
The old woman is small and frail, silver hair in a low bun, reaching only to the robot's chest.
Format, texture, camera handling and aspect ratio stated once for the whole clip.
Live-action colour feature film, 35mm grain, handheld with a breathing sway, shallow focus, 16:9.
The storyboard is line art, so rule out line art, animation and storyboard looks to keep its drawing style out of the footage.
"[Strictly exclude] ... hand drawing, sketch, line art ..."
Nine shots cover 0–30 s, each with shot size, angle and action; the ranges join end to end.
Shot 4 (10-14s): extreme long shot tilting up as the rocket climbs on a trail of white smoke.
Each line sits in its shot with the speaker named; English lines stay in English.
Line (old woman): "Fly safe, my child. Come back to me."
[References] @Image1 is the lead character's look; @Image2 is the location; @Audio1 is the lead's voice (delete this if you have none).
[Summary] A 15-second 16:9 (genre) clip: (subject) (does what) in (place), (style and texture).
[Timeline]
0-5s: (shot size, camera move) (action). Lead (mood): "..."
5-10s: (shot size, camera move) (what happens next).
10-15s: (shot size, camera move) (closing image).
[Throughout] Camera: (handheld / gimbal / locked off); light and colour: (...); sound: (ambience, action sounds; write "no background music" if you want none); no subtitles.
| Resolution | Seedance 2.5 Flash | With a reference video |
|---|---|---|
| 480P | $0.06/sByteDance list price $0.0672 · 10% below list | $0.035/sByteDance list price $0.0413 · 15% below list |
| 720P | $0.12/sByteDance list price $0.1512 · 20% below list | $0.07/sByteDance list price $0.0929 · 24% below list |
Lengths, resolutions, reference limits and prices in the table are live. Check that your references fit, then compare picture, motion and sound on your own test clips.
| Model | Length (s) | Resolution | Refs image / video / audio | Price | Good for |
|---|---|---|---|---|---|
Seedance 2.5 FlashThis pageseedance-2.5-flash |
4–30 | 480P / 720P | 10 / 5 / 5 | from $0.06/s | You want what Seedance 2.5 does, 480P / 720P is enough and the per-second price matters: bulk drafts, product clips. |
Seedance 2.5seedance-2.5 |
4–30 | 480P / 720P / 1080P | 30 / 10 / 10 | from $0.10/s | 1080P, more references, or many key frames and on-screen text that must be exact. |
Seedance 2.5 · Specialseedance-2.5-30s |
4–30 | 720P | 30 / 10 / 10 | $2.00/clip | The special tier billed per clip at a fixed 30 s (720P), when you only want long clips. |
Seedance 2.0 Fastseedance-2.0-fast |
5–15 | 480P / 720P | 9 / 3 / 3 | from $0.052/s | Clips up to 15 s where the budget comes first. |
Seedance 2.0seedance-2.0 |
5–15 | 480P / 720P / 1080P | 9 / 3 / 3 | from $0.07/s | You already have Seedance 2.0 samples and need to keep that look. |
Wan 3.0wan3.0-video |
4–30 | 480P / 720P / 1080P | 10 / 5 / 5 | from $0.04/s | You need a first frame or first + last frame, or video from a document or web page. |
MiniMax H3 Liteminimax-h3-lite |
4–15 | 480P / 768P | 5 / 0 / 0 | from $0.005/s | Bulk drafts up to 15 s at a lower rate. |
MiniMax H3minimax-h3 |
4–15 | 480P / 768P / 1080P | 9 / 3 / 3 | from $0.015/s | 1080P and first / last frames; its reference mode takes audio and video. |
Veo 3.1veo-3.1 |
8 | 720P / 1080P | 3 / 0 / 0 | $0.20/clip | Fixed-length clips billed per clip. |
Draft in Flash, finish in Seedance 2.5: the same prompt and references work on both, only model changes. In our tests with the same official cases, simple shots came out close; with many key frames or lots of on-screen text, 2.5 was more faithful (see the side-by-side above).
Log in to KovAPI and create a key in the console; one key calls every model on the site.
Sign up for KovAPIUpload reference images, videos or audio, pick length, resolution and ratio, and see the live price of the clip before you submit.
Open the playgroundSend seedance-2.5-flash to POST /v1/videos/generations and keep the job id from the HTTP 202. Already on seedance-2.5? Change only model, and mind the reference limits and resolutions.
Poll by job id, or set callback_url at submit. On success download the MP4 from data[0].url; clips are kept for 7 days.
720P is 20% below ByteDance's list price, and the rate with a reference video is below the list too. The playground shows the price of each clip before you submit.
Use photos of real people as references without masking: presenter ads, drama and talking-head clips all work. Public figures' likeness and voices are refused by review, and refused jobs are not billed.
If a job fails, the hold is refunded in full; when the upstream is busy or errors, the system retries for you.
No per-account concurrency limit: submit batches as they are; at peaks jobs queue and the API returns queue_position and eta_seconds, with a webhook when done.
Every case on this page is a real render at its original settings, with its cost; the side-by-side with Seedance 2.5 and the render times are reported as they came out, good or bad.
Sign up with email, Google or GitHub; top up by card, PayPal, WeChat or USDT; pay as you go with no subscription. The same key calls the chat and image models too.
Dates as ByteDance announced them; what KovAPI offers today is in the modes table above.
ByteDance Seed releases Seedance 1.0, with 1080P and multi-shot storytelling.
Sound generated together with the picture for the first time.
Text, image, video and audio inputs; up to 15 s per clip; up to 9 images, 3 videos and 3 audio clips as references.
Up to 30 s per clip; 30 reference images and 10 reference videos and audio clips each; shots on whole-second timestamps.
Announced on 12 November 2026, API open from the 15th. Same prompts as 2.5 and up to 30 s per clip; references up to 10 images, 5 videos and 5 audio clips; 480P / 720P only. ByteDance says it generates about twice as fast as 2.5.
seedance-2.5-flash: text to video and generation from reference images, videos and audio, with sound, up to 30 s per clip.queue_position and eta_seconds; the job status is what counts.audio: false has no effect. To leave out music or voices, write "no background music" or "no dialogue" in the prompt.model to seedance-2.5-flash; every other field is the same. Mind Flash's reference limits (10 images / 5 videos / 5 audio) and resolutions (no 1080P): anything over is refused at submit with a 400.Explore other models you can integrate.

Text / image to video · up to 30 seconds
Low latency · quick turnaround
Text / image to video · 5-15 seconds
One endpoint, five modes · up to 30 seconds
Faster, cheaper H3 · 480P / 768P
Entry tier · lowest cost
Have a question, partnership idea, or feedback? Feel free to reach out.
lz15526267716Scan with WeChat, or search for the ID